How did Microsoft Windows become a gaming platform?
Early versions of Windows lacked the fast CPU pixel-filling and display negotiation needed for games, so developers like Chris Hecker created a skunkworks library called WinG to enable fast screen blitting. This unapproved graphics add-on served as the direct institutional and technical precursor to DirectX, which eventually established Windows as a dominant gaming platform. Although management volatility temporarily disrupted the project, it successfully proved that Windows could handle high-performance graphics.
What makes Rust a good choice for systems programming?
Rust is a compiled, memory-safe programming language that combines high-level simplicity with low-level performance. It is commonly used for building systems where performance is critical, such as game engines, databases, operating systems, and web assembly targets.
How did you approach building the backend message threading for Gmail?
Peter and the team utilized B-trees and inverted search indices to handle message threading and unread counts right from the start. This architecture supported fast lookups despite the constraints of early distributed systems.
Why do standard unit and integration test suites miss critical production bugs?
Standard test suites only check components in isolation and rely on situations developers have actively anticipated. Production failures are usually caused by environmental factors, weird timing, or complex interactions that engineers never thought to test for.
Why does tokenization cause weird issues like poor spelling or arithmetic in LLMs?
Tokenization acts as the fundamental boundary layer for text, meaning that string manipulations and non-English text are often poorly represented. Simple tasks like spelling or arithmetic fail because the model sees arbitrary subword chunks instead of characters or proper words.
How do I inspect the tensor shapes of the original GPT-2 checkpoint?
You can load the model using Hugging Face Transformers and extract its state dictionary to inspect key-value tensor shapes. This reveals the dimensions of components like the 50257-by-768 token embedding lookup table.
Why do most engineering teams and developers ignore software performance?
Developers often overlook performance because enterprise software purchasers care more about compliance and cost than speed, and monopoly network effects make responsiveness secondary to user acquisition. Furthermore, a general lack of awareness regarding hardware limits leads to poor benchmarking and bloated software budgets. However, recent trends show that startups using performance-based pitches are starting to gain traction against sluggish incumbents.
How does Rust handle memory management without a garbage collector?
Rust achieves memory safety through a system of ownership and borrowing instead of using a garbage collector. By default, variables are immutable and stored on the stack, while mutable values or unknown sizes go to the heap. When a variable goes out of scope, its allocated memory is dropped automatically.
Why did Colossus transition from traditional replication to Reed-Solomon erasure coding?
Traditional replication required storing three identical copies of data, which consumed excessive storage space. Reed-Solomon erasure coding allowed the system to store data much more efficiently while still allowing data reconstruction if multiple chunks were lost.
How do you specify high-level invariants for a massive distributed system without going crazy?
You start with a small number of basic properties like ensuring the system never crashes or times out. As you go deeper, you can turn formal API guarantees and written SLAs into automated test properties.
Why do non-English languages and Python code waste context window space in GPT-2?
GPT-2's tokenizer breaks non-English text and Python indentation spaces into many small, separate tokens. This bloats the sequence length and causes the model to run out of context length during attention.
How are positional embeddings structured in GPT-2 compared to the original Transformer?
Unlike the original Transformer which used fixed sinusoidal functions, GPT-2 treats positional embeddings as trainable parameters initialized randomly from scratch. During optimization, these embeddings organically develop smooth sinusoidal and cosine structures.
How should I actually approach optimizing software performance?
True optimization requires identifying the theoretical peak capabilities of the underlying hardware and measuring the performance delta against your current implementation. Relying solely on a profiler to find big bottlenecks only traps you in local minima without knowing what the machine is truly capable of achieving. Calculating theoretical maximums also helps engineers discover hardware anomalies and continuously learn about modern CPU architectures.
Borrowing allows parts of a program to access a reference in memory without taking ownership of it. The Rust borrow checker validates a strict set of rules at compile time to ensure code safety while maintaining performance control.
Why are B-trees often preferred over binary trees for memory performance?
Standard balanced binary trees cause frequent cache misses because every node traversal jumps to a different cache line. B-trees improve spatial locality and reduce pointer overhead by packing multiple sorted items into a single node. This structure allows more compact storage and faster linear scans or binary searches over items.
Why do relaxed specifications make property-based tests more maintainable than traditional UI tests?
Traditional tests rely on rigid sequences of steps that break when completely incidental changes occur. Property testing checks general rules and invariants, meaning incidental updates like level layouts or timing don't automatically break your tests.
Why can't we just use raw Unicode code points directly as inputs to language models?
While Unicode provides integers for characters, the standard encompasses roughly 150,000 characters and is constantly changing. Using them directly would create an unstable vocabulary and an unnecessarily large embedding space.
What architectural changes did GPT-2 make to the original Transformer layer normalization?
GPT-2 moves the layer normalizations before the attention and multi-layer perceptron blocks rather than after them. It also adds an extra layer normalization right before the final classification head to maintain a clean residual stream.
Why should I learn assembly language if I never write it?
Reading assembly is essential because it reveals the exact instructions the CPU is being asked to execute, unlike high-level languages which only show input to a compiler. It is surprisingly simple, requiring you to learn only a small subset of instructions that compilers actually output. Once you know it, you can read hardware architecture diagrams and understand CPU performance directly.
You can get started by installing Rust and using its package manager, Cargo. Running cargo new from the command line creates a new package, where individual packages are known as crates.
How do distributed databases differ fundamentally from distributed storage systems?
Distributed storage systems like Colossus target large, immutable, append-only files such as 64-megabyte or gigabyte chunks. In contrast, distributed databases like Spanner manage relational tables with billions of typed rows and columns requiring frequent updates. Databases are typically built on top of distributed storage systems, using immutable files and log-structured merge trees to handle updates.
How does the hypervisor run unmodified Linux deterministically without modifying the kernel?
The hypervisor implements a deterministic machine model underneath standard Linux so operations always take predictable clock cycles. When the system attempts a non-deterministic call like getting a random number, the hypervisor traps it and returns a deterministic answer.
How does the Byte Pair Encoding algorithm compress text sequences?
BPE iteratively scans a sequence to find the most frequently occurring pair of tokens. It then mints a new vocabulary token for that pair and replaces all instances of it throughout the sequence.
Which activation function does GPT-2 use in its MLP blocks?
GPT-2 uses an approximate version of the Gaussian Error Linear Unit activation function backed by a tanh approximation. This avoids the flat zero-gradient regions seen in standard ReLUs and provides smooth, continuous gradients during optimization.
What is a false serial dependency chain and how does it hurt performance?
A serial dependency chain occurs when operations must happen in a specific order, such as waiting for a network request to finish before doing the next calculation. Because performance is determined by the longest un-parallelizable chain, this architectural pattern cannot be easily fixed by localized hotspot optimization. Avoiding it requires designing architectures that batch requests upfront and only chain when strictly necessary.
Variables are declared with the let keyword and are immutable and unchangeable by default. To make a variable mutable so its value can be reassigned, you must add the mut keyword.
How does contiguous key range sharding differ from basic hash-based sharding?
Basic hash-based sharding maps keys to a fixed number of shards using a hash function, which makes resharding and growing the table an onerous process. In contrast, systems like Cockroach DB use contiguous key spans across a single big key space, partitioning them with a B-tree-like index structure. This avoids full table remappings when adding nodes and places the sharding burden on the database rather than the developer.
How does time-travel simulation speed up finding deep multi-step bugs?
Determinism allows the hypervisor to restart the simulation from the beginning and follow the exact same path without saving heavy state snapshots. Once a rare intermediate event is reached, the system locks it in and only explores further paths from that point onward, drastically reducing exponential search times.
How do I replace a specific token pair across an ID list?
You iterate through the token list sequentially and check if the current and next positions match the target pair. If a match is found, you append the new replacement index and advance the pointer by two to skip the pair. Otherwise, you just copy the single element over and increment by one.
How do I prepare text data into batches for Transformer training?
Tokenize the text into a sequence of integers and view it as a two-dimensional batch tensor. You should fetch an extra token beyond the sequence length so you can create parallel input and target tensors offset by one position.
What basic CPU mechanics do I need to understand for better software design?
You should understand how data moves through load store units and cache hierarchies like L1, L2, and L3 caches to optimize data access patterns. It is also helpful to conceptualize instruction flow, branch misprediction, and execution unit scheduling throughput. Knowing these components allows you to make informed architectural choices that keep your software performant without needing to be a hyper-optimizer.
Why does Raft consensus require at least three replicas to work?
Consensus protocols like Raft cannot function with only two replicas because a crash leaves it impossible to determine if a write successfully occurred on the other node without data loss or rollback ambiguities. Having at least three replicas allows the system to perform consensus checks during recovery by reading from a quorum. Normal reads can still hit a single replica, while writes go to all three to ensure durability.
What clues does the platform use to recognize that something interesting has happened?
The system monitors which lines of code or new functions run by tracking call stacks or developer-added callbacks. It also scans log messages for specific errors and watches control flow branches, such as unexpected loop or conditional branch outcomes, to guide further exploration.
Why does decoding certain token sequences throw a UTF-8 error?
Invalid UTF-8 errors occur because not every arbitrary byte sequence or poorly predicted language model token forms a valid Unicode character envelope. To prevent crashes when encountering invalid start bytes, you should set the decode error handling parameter to replace.
What is the expected initial cross-entropy loss for a random model?
The expected initial loss corresponds to the negative natural logarithm of a uniform probability distribution over the vocabulary. For a vocabulary size of 50,257, this evaluates to roughly 10.82, which sanity checks our initialization.
How did the rise of licensable game engines change the indie and AAA games market?
Licensable engines eliminated the massive technical risk of building engines from scratch, allowing many more creators to publish games. However, this drastically flooded storefronts like Steam, making organic discovery nearly impossible and turning marketing and distribution into the true differentiators. Additionally, games now compete not just against new releases, but against timeless older titles and always-on live services.
How do I manage multiple agent sessions effectively when coding with AI?
Managing multiple agent sessions involves handling a cognitive overhead of about five to ten concurrent sessions. Depending on the complexity of the task, these sessions can orchestrate anywhere from three to over a hundred sub-agents running in parallel to perform research or implementation. This allows developers to act more like hands-on architects scaling their throughput.
How do you alter execution paths if you aren't storing the entire machine state?
The platform uses a special shim that intercepts every request for a random number from a controlled random source. By periodically changing a single register or decision value at a specific instruction count, it can force the system to branch down entirely different execution paths.
How do I encode text back into tokens using trained merges?
You start by encoding the raw text into UTF-8 bytes and casting it to a list of integers. Then, in a loop, you find all consecutive pairs using statistics and pick the one with the lowest index in your merges dictionary. You repeat this replacement process until no more eligible pairs can be merged.
How do I handle multi-dimensional tensors when calculating cross-entropy loss?
PyTorch's cross entropy function cannot accept multi-dimensional inputs directly. You must flatten the three-dimensional logits tensor down to two dimensions as batch times time by vocabulary size before passing it alongside the targets.
Why do clean code rules like excessive small functions and polymorphism degrade performance?
Rules that mandate polymorphism and tiny functions fundamentally block compilers from performing crucial optimizations like inlining and code collapsing. When a compiler cannot determine runtime behavior or potential class substitutions, it cannot optimize the execution path. The actual performance cost stems from the loss of compiler optimization capabilities rather than the virtual function call itself.
How do I prevent quality and security regressions when AI generates large amounts of code?
To prevent regressions, developers must provide firm guidance and enforce rigorous testing techniques like property-based testing and deterministic simulation testing. Agents can sometimes be lazy with tests, so humans need to instill discipline and use multiple agents for adversarial security reviews on every commit. This ensures that the high volume of generated code still meets production standards.
What types of real-world systems are currently adopting this whole-universe testing approach?
Initial adoption is strongest among data infrastructure, distributed computational frameworks, and databases like Confluent and MongoDB. It is also widely used by blockchain and fintech companies where the financial cost of a production bug is catastrophic.
Why do LLM tokenizers use a regex splitting pattern before merging?
A regex splitting pattern chunks text into independent categories like letters, numbers, and punctuation before applying merges. This prevents suboptimal cross-category merges, such as combining common words with adjacent punctuation marks into a single token.
Why is weight tying used in Transformer models like GPT-2?
Weight tying reuses the same weight matrix between the bottom token embeddings and the top language modeling head. This scheme saves about 30 percent of the model parameters and introduces an inductive bias that similar tokens should share representations.
What is a pragmatic approach to testing and test-driven development?
Development should not be blindly driven by tests by default, as rigid testing requirements can make codebases harder to change and maintain. Instead, engineers should pragmatically evaluate whether the cost of creating and maintaining tests is outweighed by the bugs they prevent.
How is code review changing in the age of AI coding agents?
Code review is shifting because developers spend less time scrutinizing code as agents improve and guardrails are put in place. While junior-level code still requires high scrutiny, senior developers rely on automated verification and guardrails—such as checking decompiled code for zero-overhead abstractions—rather than manual line-by-line review. Eventually, this leads to trusting compilers and automated tools to verify low-level output.
What are special tokens used for in language model tokenizers?
Special tokens are used to delimit training documents, structure conversation turns between users and assistants, or enable features like fill-in-the-middle. They operate outside standard bpe merges and require extending the model's embedding matrix and final classifier layers.
How are the weights initialized according to the GPT-2 specifications?
Linear layer weights are initialized from a normal distribution with a standard deviation of 0.02, while biases are set to zero. Additionally, residual layer weights are scaled down by the square root of the number of residual layers to prevent activation growth.
How does developer autonomy influence the experience of using AI tools?
Developers with a high degree of autonomy view AI tools positively, using them optionally to eliminate tedious tasks. Conversely, engineers who lack control and are mandated by management to use AI under strict output pressure often experience burnout and fear automation of their roles.
How can domain experts leverage AI models effectively for complex software development?
Domain experts act like amplified sorcerers when using AI, leveraging their deep knowledge of system architecture to steer models effectively. By knowing the right architectural patterns—such as storage and networking layers for distributed databases—experts can extract high-quality, complex implementations rapidly. Without that underlying domain expertise, the generated output tends to be hollow and lacking substance.
How does SentencePiece differ from Tiktoken in its core approach?
SentencePiece operates directly on raw code points rather than utf-8 encoded bytes and uses a character coverage parameter to handle rare characters. It also includes extensive historical configuration options along with fallback behaviors for handling rare or unknown tokens.
How does tensor float 32 speed up matrix multiplications?
Tensor float 32 maintains the standard sign and eight exponent bits of a 32-bit float but truncates the mantissa down to 19 bits. This reduction happens internally within the GPU tensor core instruction, allowing matrix multiplications to execute significantly faster. Because the accumulation and outputs remain in float32, this approximation is empirically unnoticeable during deep learning training.
Why does reading technical papers build deep expertise?
Reading technical papers allows developers to uncover historical context, trace reference chains, and discover entirely new programming techniques. This deep dive approach helps programmers expand their domain knowledge far beyond standard books or blogs.
What factors limit how large a vocabulary size can be?
Increasing vocabulary size expands the token embedding table and the final linear layer, increasing computational cost and parameter count. Furthermore, rare tokens appear less frequently in training data leading to undertrained vectors, and excessively large chunks reduce the model's processing time per character.
Why is GPU synchronization necessary when timing training iterations?
Because the CPU asynchronously schedules work and queues up kernels to run on the GPU, execution does not happen instantly. Without explicit synchronization, code timing measurements can capture just the CPU scheduling duration rather than the actual GPU workload execution time. Calling CUDA synchronize forces the CPU to wait until the GPU finishes all scheduled work before taking timestamps.
How does tokenization impact an LLM's ability to spell or reverse words?
Words are chunked into multi-character tokens where too much information is crammed into a single unit, impairing character-level tasks like spelling or string reversal. When forced to process text broken down into individual characters instead of large pre-merged tokens, the model performs significantly better.
How does torch compile eliminate Python overhead and fuse kernels?
Torch compile analyzes the entire neural network structure ahead of time instead of executing operations sequentially through the python interpreter. It identifies element-wise operations and performs kernel fusion to keep data chunks on the GPU chip for multiple calculations. This avoids expensive round trips between high bandwidth memory and processing units, significantly speeding up training throughput.
Why do trailing spaces cause warnings and poor performance in completion models?
Space characters are typically prepended to subsequent tokens, meaning a trailing space isolates a token boundary and forces the model out of its training distribution. Since the model rarely sees isolated trailing space tokens, predicting from this state causes unpredictable behavior or premature stopping.
How does FlashAttention speed up Transformer models?
FlashAttention fuses attention operations and avoids materializing the massive attention matrix in high-bandwidth memory. Even though it performs more total floating-point operations, it drastically reduces expensive HBM memory round trips and speeds up execution significantly.
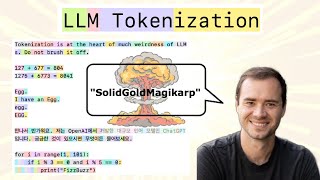
What causes solid gold Magikarp bugs in language models?
These bugs occur when strings common in the tokenization dataset—such as specific Reddit usernames—are merged into dedicated tokens but are entirely absent from the actual model training data. Consequently, those embedding vectors remain completely uninitialized and untrained, acting like unallocated memory that triggers undefined behavior at test time.
Why should I pad the vocabulary size to a power of two?
Padding awkward vocabulary sizes like 50257 to powers of two like 50304 helps Cuda kernels execute more efficiently using standard block tiles. Although it introduces slight compute overhead, it prevents inefficient boundary kernels and improves performance by several percent.
What does gradient norm clipping prevent during training?
Gradient norm clipping caps the global norm of parameter gradients at a specified threshold like 1.0. This prevents occasional bad data batches from causing massive gradient spikes that could destabilize or shock the model optimization.
How do I implement cosine decay with warmup for learning rates?
A cosine decay schedule starts with a linear warmup phase from near zero up to a maximum learning rate, followed by a cosine curve down to a minimum rate. While PyTorch has built-in schedulers, writing a custom function over iteration steps offers clear transparency and full control.
Why should I separate weight decay for 1D and 2D parameters?
Weight decay regularizes models by preventing weights from growing too large, but it should not be applied to 1D tensors like biases and layer norm scales. Instead, weight decay is restricted to 2D matrix multiplication weights and embeddings to properly distribute work across channels.
How can I simulate large training batch sizes with limited GPU memory?
Gradient accumulation lets you process multiple smaller micro-batches sequentially while adding up their gradients via backward passes. Once the target token count is reached across these steps, a single optimizer update is performed to simulate a massive batch size.
How do I run training across multiple GPUs using DDP in PyTorch?
Launch your training script using the torchrun command, which automatically sets up environment variables like rank and world size for parallel processes. Each process assigns itself to a specific CUDA device using its local rank and runs an identical copy of the model.
How do I prevent data loaders from feeding the exact same data to every GPU?
Modify your data loader to accept the process rank and total number of processes to stride through dataset chunks. Each rank initializes at a different offset and advances its position by the total number of processes multiplied by the batch size and sequence length.
How should I handle gradient synchronization when using gradient accumulation with DDP?
By default, DDP synchronizes gradients across all GPUs after every backward pass, which is wasteful during intermediate gradient accumulation steps. You can avoid this by toggling require_backward_grad_sync to false during intermediate micro-steps and enabling it only on the final step before the update.
How do I prepare and structure large web datasets for pre-training?
You can write a script to download the dataset from Hugging Face, tokenize the documents with special start tokens, and save them into fixed-size numpy file shards on disk. Using uint16 arrays saves space, and sharding into chunks of 100 million tokens makes large datasets much easier to manage during training.
How do I implement HellaSwag evaluation without multiple-choice capability?
Since small models cannot handle multiple-choice labels directly, you construct a batch of token completions pairing the shared context with each of the four possible options. You then evaluate the cross-entropy loss or token probabilities for each option and pick the one with the highest average probability.
How do I structure a multi-epoch training run and save checkpoints?
You can scale up training by multiplying your epoch count such as running four epochs for an overnight run while periodically saving model checkpoints alongside optimizer states. Saving the optimizer state dictionary is essential for preserving Adam buffers like m and v if you intend to resume optimization later.
How does supervised fine-tuning transition from pre-training?
Transitioning to supervised fine-tuning involves swapping out the pre-training text dataset for a conversational one with a user-assistant structure. You continue training by filling in user tokens and sampling assistant tokens, which adapts the document-dreaming model into a conversational chat format.
How does a pure C and CUDA implementation compare to PyTorch?
You can implement a parallel training loop in pure C and CUDA to achieve faster startup and higher tokens-per-second performance than general frameworks like PyTorch. While PyTorch handles general neural networks, a dedicated implementation like llm.c directly targets GPT architectures to squeeze out maximum hardware speed while producing identical loss curves.
 ▶ 8:07
Why performant code matters (but gets widely ignored), with Casey Muratori